
VeloxQuant-MLX
Run bigger local LLMs in less memory, on Mac
What is VeloxQuant-MLX?
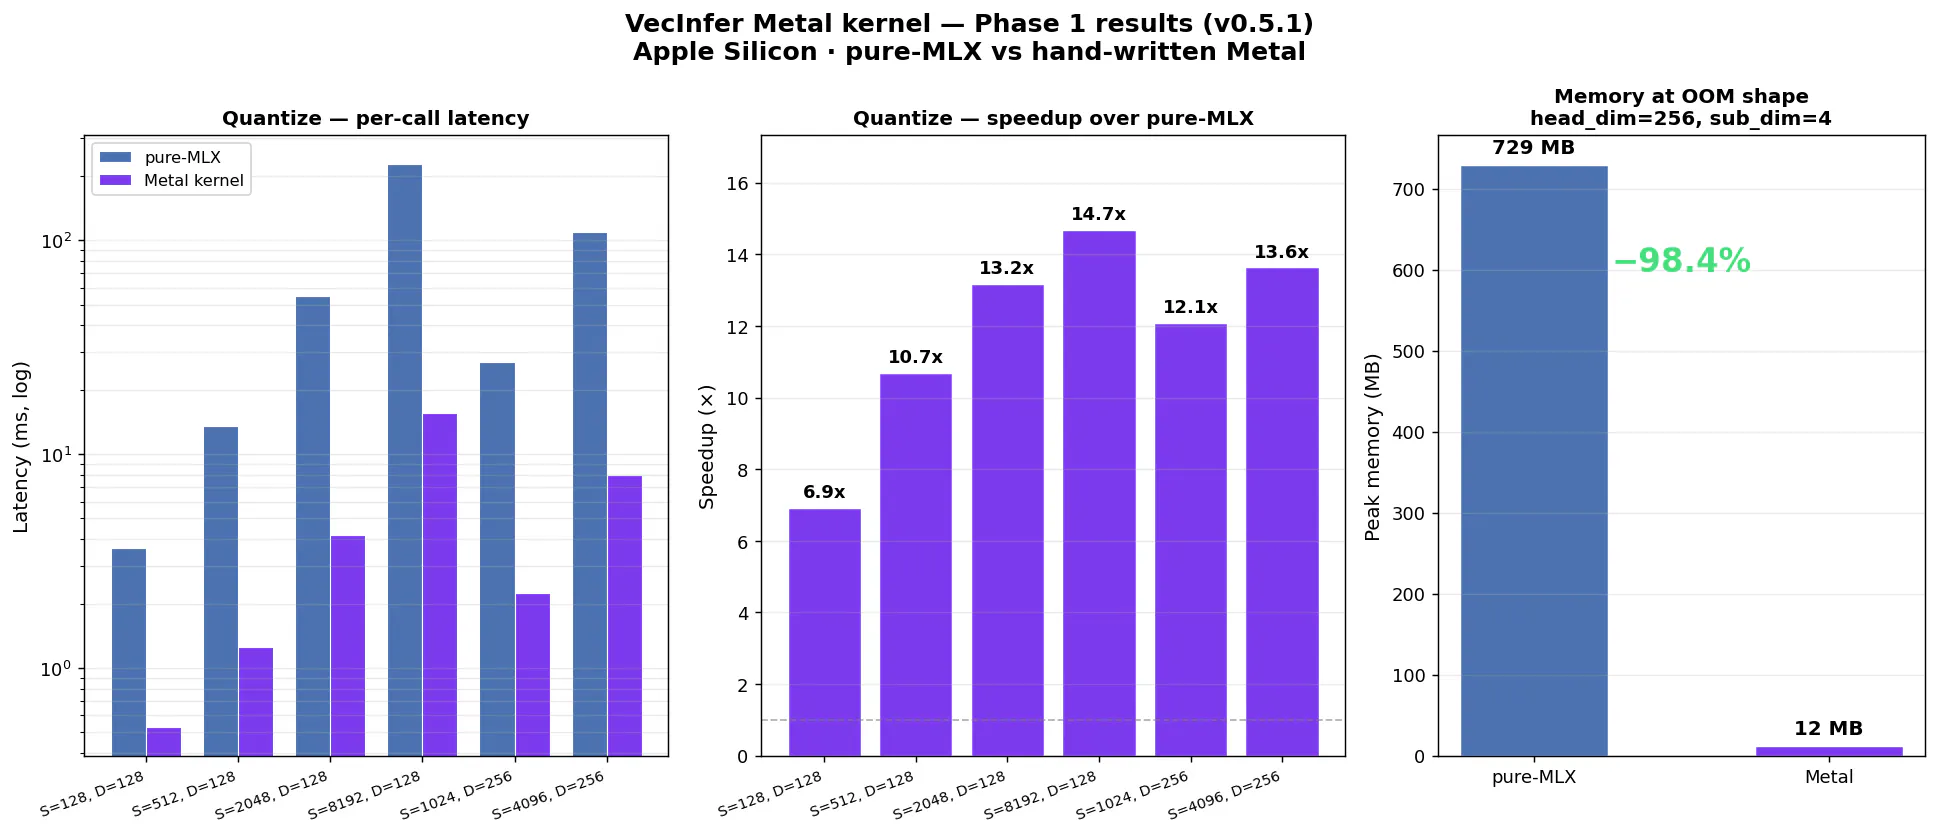
VeloxQuant lets you run bigger local AI models in less memory, fully private with no cloud required. One simple API compresses memory usage up to 16x while keeping generation fast on Apple Silicon.
Screenshots
?
No comments yet. Be the first!