
Throttle
Smart routing for LLM inference, save thousands on API costs
What is Throttle?
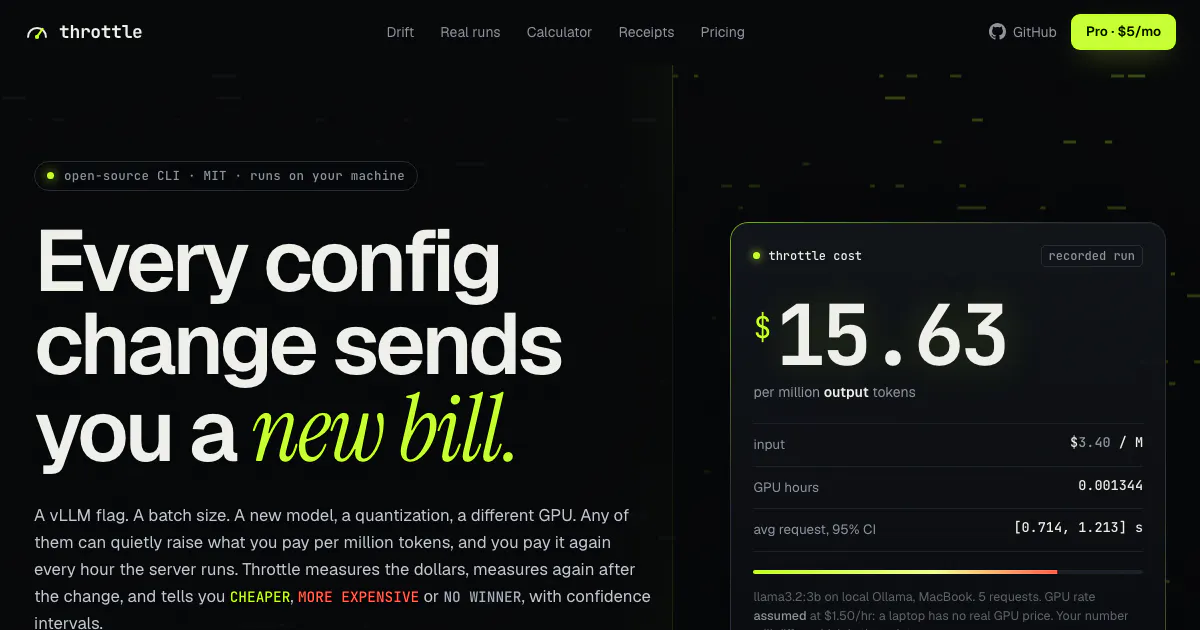
We built Throttle because teams are bleeding money on LLM inference. Your bill keeps climbing even though you're not using better models. Throttle sits between your code and Claude/OpenAI, automatically routes requests to cheaper models when quality isn't sacrificed, caches intelligently, and batches efficiently. Result: 70% cost cuts, same performance. Built for startups and companies already paying $1000+/month on inference.
Screenshots
?
No comments yet. Be the first!